Streaming
Workflows can stream data to clients in real time without waiting for the entire workflow to complete. Clients can receive progress updates, AI-generated content, log messages, and other incremental data as workflows execute.
Getting started with getWritable()
Every workflow run has a default writable stream that steps can write to using getWritable(). Data written to this stream becomes immediately available to clients consuming the workflow's output.
Consuming the stream
Use the Run object's readable property to consume the stream from your API route:
When a client makes a request to this endpoint, they'll receive each message as it's written, without waiting for the workflow to complete.
Avoiding function timeouts after client disconnects
On Vercel, run.readable and run.getReadable() reconnect to Workflow's stream storage while the workflow is still running. By default, a client disconnect does not terminate the Vercel Function serving the stream. If a user closes the page or stops the request, the function can therefore keep reconnecting until it reaches its maximum duration and fails with FUNCTION_INVOCATION_TIMEOUT.
For streaming routes using the Node.js runtime, opt in to request cancellation in vercel.json:
Replace the function path with the path or glob for your streaming route. When the downstream client disconnects, Vercel terminates the matching function invocation instead of leaving its stream reader running. The workflow run and its durable stream continue independently, so the client can reconnect through another route invocation later.
Cancellation applies to every function matching the configured path or glob, even if the route does not listen to request.signal. Any other work in that invocation which is not wrapped in waitUntil or after can be lost. Only enable it for routes that are safe to terminate when their client disconnects.
This setting prevents abandoned stream readers from consuming the rest of a function invocation. It does not extend the function's maximum duration. An actively connected streaming response can still reach the configured limit, at which point the client should reconnect to the durable stream.
Resuming streams from a specific point
Use run.getReadable({ startIndex }) to resume a stream from a specific position. This is useful for reconnecting after timeouts or network interruptions:
Clients can reconnect and continue receiving data from where they left off instead of restarting from the beginning.
startIndex also supports negative values to read relative to the end of the stream. For example, startIndex: -5 starts 5 chunks before the current end. This is useful when you want to show the most recent output without reading the entire stream history.
On an active (not-yet-closed) stream, the negative index resolves relative to the chunk count at connection time; any chunks written afterward are still delivered normally.
If the absolute value exceeds the total number of chunks, reading starts from the beginning (the value is clamped to 0).
Because streams are live and continue receiving chunks, negative startIndex values resolve to different absolute positions on each call. Accurate pagination over a live stream requires cursor-based access, which is not yet supported. Keep this in mind when building clients that paginate over stream data.
Streams as data types
ReadableStream and WritableStream are standard Web Streams API types that Workflow SDK makes serializable. Workflow SDK lets you pass these standard types between functions while maintaining their streaming capabilities.
Unlike regular values that are fully serialized to the event log, streams maintain their streaming capabilities when passed between functions.
Key properties:
- Stream references can be passed between workflow and step functions
- Stream data flows directly without being stored in the event log
- Streams preserve their state across workflow suspension points
How streams persist across workflow suspensions
Persistent, resumable storage from the World implementation lets Workflow SDK streams maintain their state when workflows suspend and resume:
- Vercel deployments: Streams are backed by a performant Redis-based stream
- Local development: Stream chunks are stored in the filesystem
Passing streams as arguments
Because streams are serializable data types, you don't need to use getWritable(). You can pass your own streams as arguments from outside a workflow into steps.
The following example passes a request body stream through a workflow to a step that processes it:
Important limitation
Streams cannot be used directly in workflow context
You cannot read from or write to streams directly within a workflow function. All stream operations must happen in step functions.
Workflow functions must be deterministic to support replay. Streams bypass the event log for performance, so reading stream data in a workflow would break determinism because each replay could see different data. Requiring all stream operations to happen in steps ensures consistent behavior.
For more on determinism and replay, see Workflows and Steps.
Namespaced streams
Use getWritable({ namespace: 'name' }) to create multiple independent streams for different types of data. This is useful when you want to separate logs, metrics, data outputs, or other distinct channels.
Consuming namespaced streams
Use run.getReadable({ namespace: 'name' }) to access specific streams:
Writing to another run's stream
getRun(runId).getWritable() appends to a stream owned by another run. This lets short-lived runs contribute to a long-lived holder run's stream using only its ID.
Pass { namespace: "name" } to target a namespaced stream. The writable can also be forwarded through start() and into steps.
Contributors should call releaseLock(), which flushes pending writes. Calling close() closes the shared stream for every writer. Calling abort() keeps the chunks already written and leaves the shared stream open.
The API grants append access, not read access or additional authorization. The owning run controls the stream's lifecycle, and writes to an unknown run fail.
Common patterns
Progress updates for long-running tasks
Send incremental progress updates to keep users informed during lengthy workflows:
Streaming AI responses with WorkflowAgent
Stream AI-generated content using AI SDK's WorkflowAgent from @ai-sdk/workflow. The agent writes ModelCallStreamPart chunks to the workflow stream, and route handlers convert them to UI message chunks with createModelCallToUIChunkTransform() before returning the response:
For the full agent API and migration notes, see the WorkflowAgent documentation.
Streaming between steps
One step produces a stream and another step consumes it:
Processing large files without memory overhead
Process large files by streaming chunks through transformation steps:
Best practices
Batching and first-chunk latency:
Writes are flushed immediately by default. The leading chunk of an idle stream dispatches as soon as it is written, and chunks arriving while a flush is in flight coalesce into the next batch. If you write bursts of many tiny chunks and prefer fewer round trips over first-chunk latency, set a group-commit window with the World's streamFlushIntervalMs option or the WORKFLOW_STREAM_FLUSH_INTERVAL_MS environment variable. See Worlds configuration.
Release locks properly:
Stream locks acquired in a step only apply within that step, not across other steps. This enables multiple writers to write to the same stream concurrently.
If a lock is not released, the invocation that ran the step cannot terminate. Even though the step returns and the workflow continues, the underlying request remains active until it times out and wastes compute resources.
Close streams when done:
Streams are automatically closed when the workflow run completes, but explicitly closing them signals completion to consumers earlier.
Use typed streams for type safety:
Stream failures
When a step returns a stream, the step is considered successful once it returns, even if the stream later encounters an error. The workflow won't automatically retry the step. The consumer of the stream must handle errors gracefully. For more on retry behavior, see Errors and Retries.
Stream errors don't trigger automatic retries for the producer step. Design your stream consumers to handle errors. Because the stream is already in an errored state, retrying the consumer won't help. Use FatalError to fail the workflow immediately.
Performance
Chunk trip time (CTT) measures how quickly a chunk written to a stream reaches its reader: the clock starts when one step writes the chunk and stops when another step receives it. The animation shows a writer step replaying a recorded agent stream and a reader step receiving each chunk.
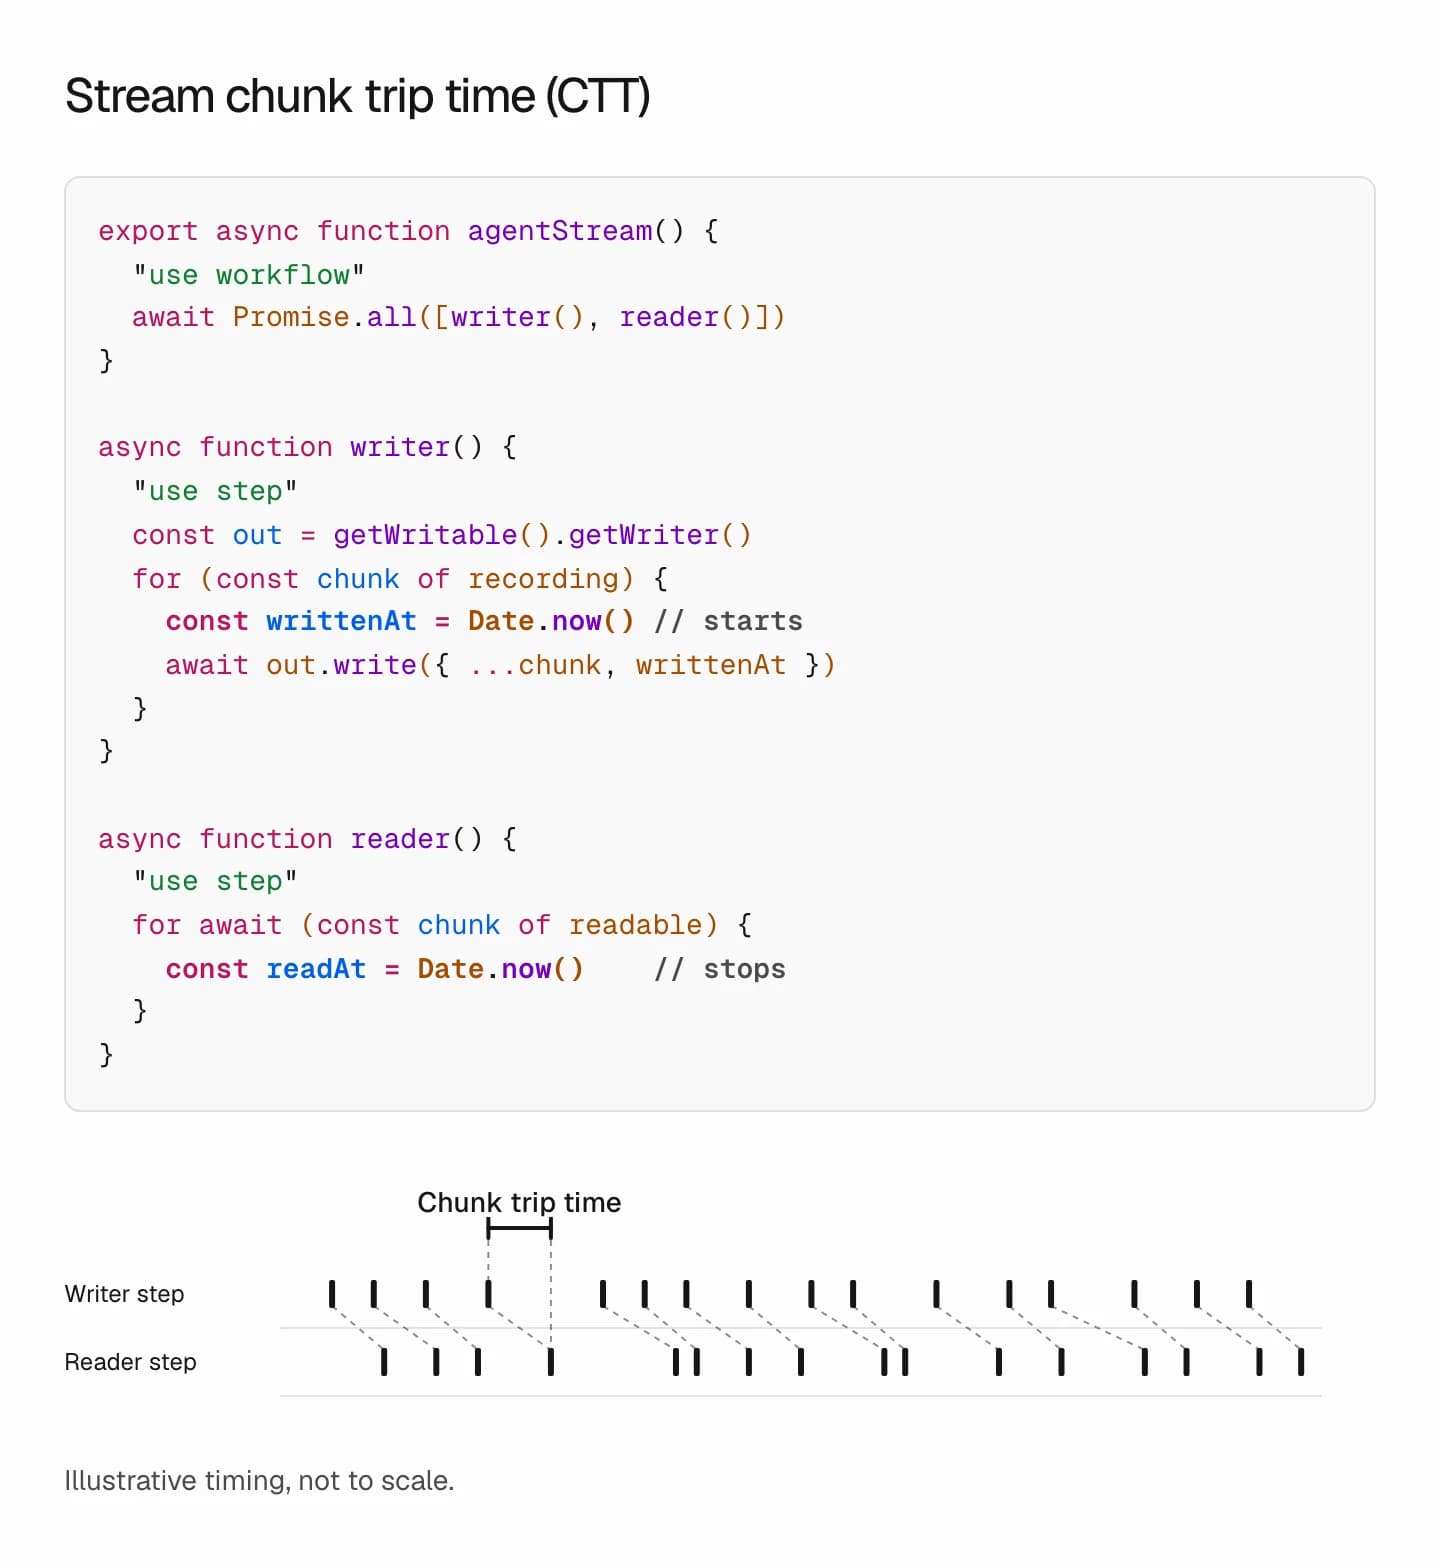
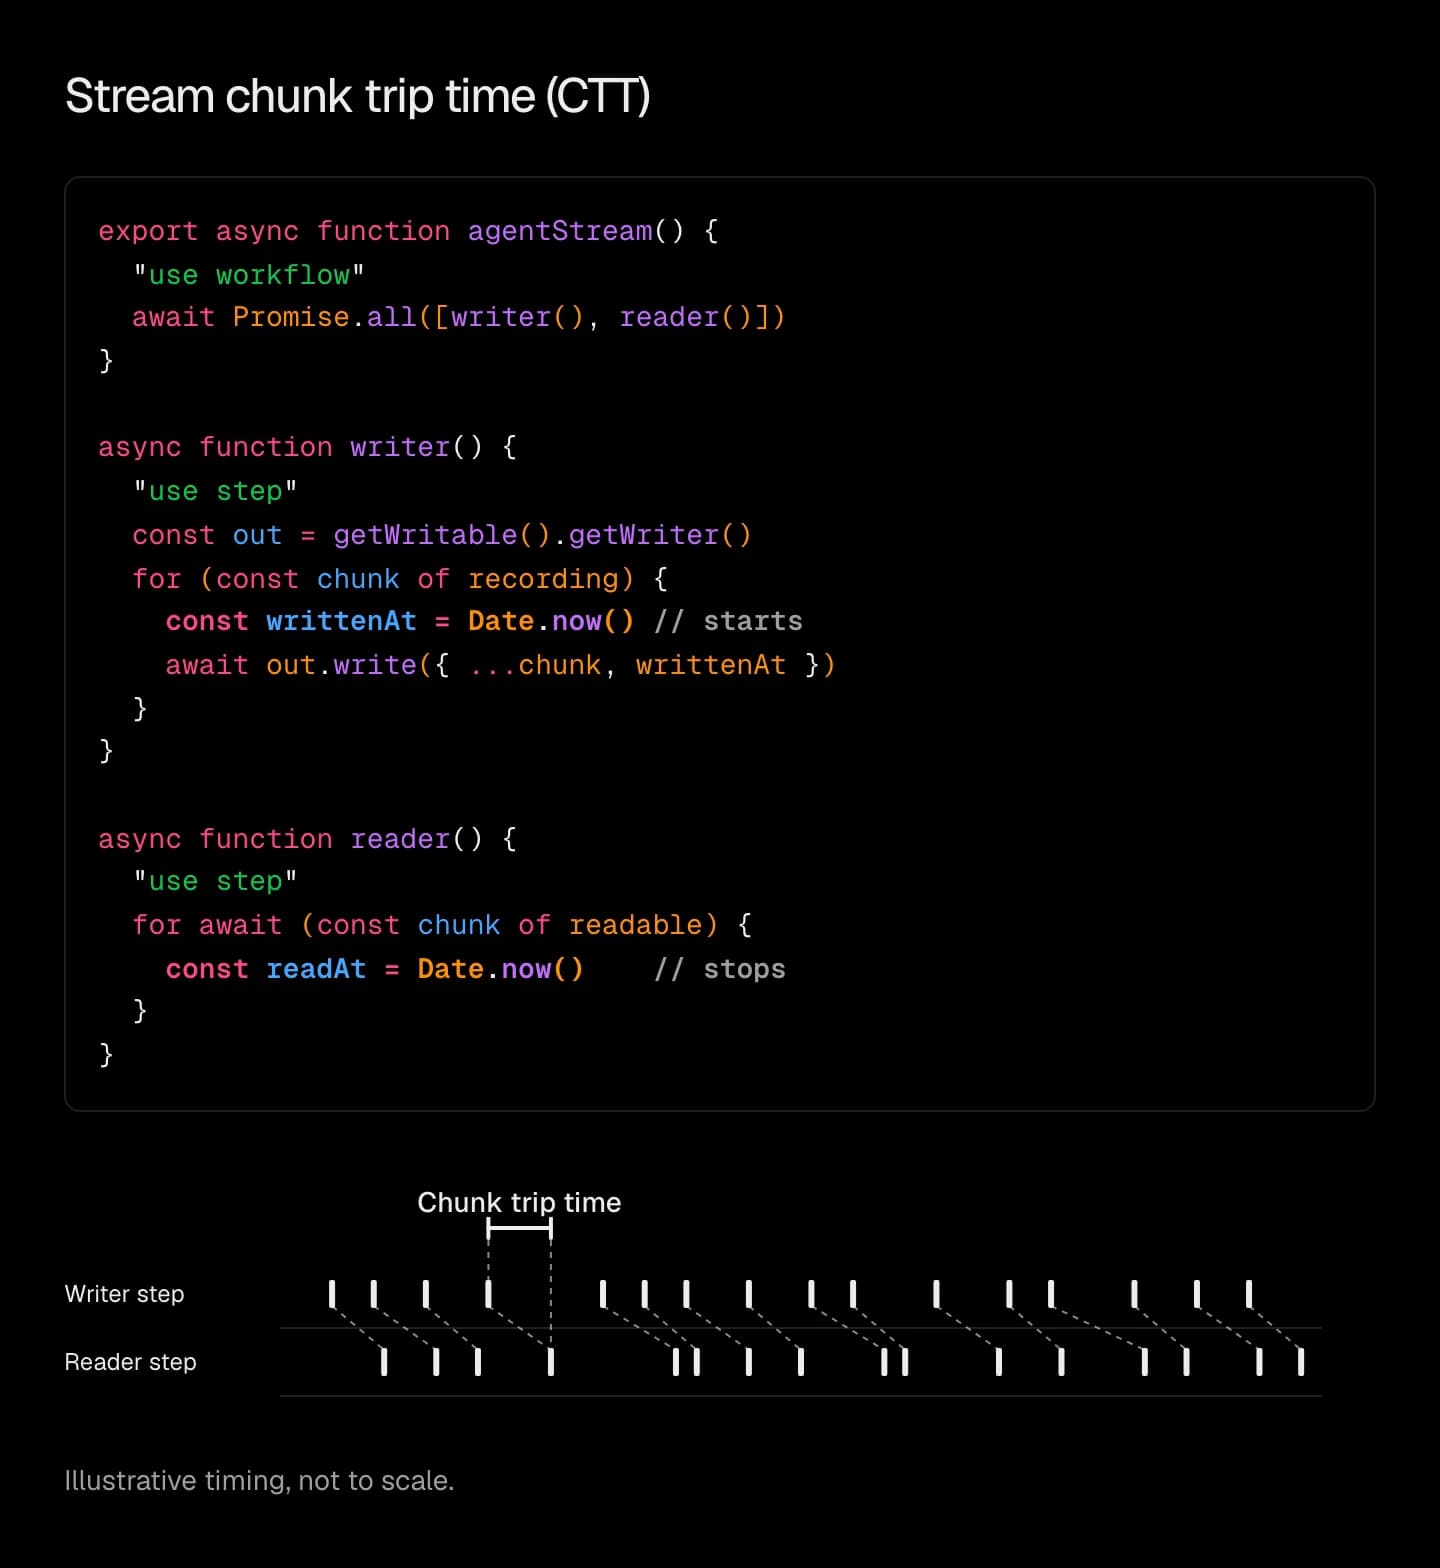
See Chunk trip time on the Performance page for how it's measured and the latest results.
Related documentation
getWritable()API reference: Get the workflow's writable streamsleep()API reference: Pause workflow execution for a durationstart()API reference: Start workflows and access theRunobjectgetRun()API reference: Retrieve runs and their streams laterworld.streams: Use low-level stream read, write, and close operations through the World SDKWorkflowAgent: Build AI agents with durable, resumable streaming support- Errors and retries: Understand error handling and retry behavior
- Serialization: Understand which data types you can pass in workflows
- Workflows and steps: Learn the core concepts of workflow execution